How to Tell Whether Your GEO Campaign Is Actually Improving AI Visibility
Learn how to measure whether a GEO campaign is improving your brand’s visibility in AI-generated answers. This guide explains the metrics, monitoring process, and reporting framework that separate real progress from noise.
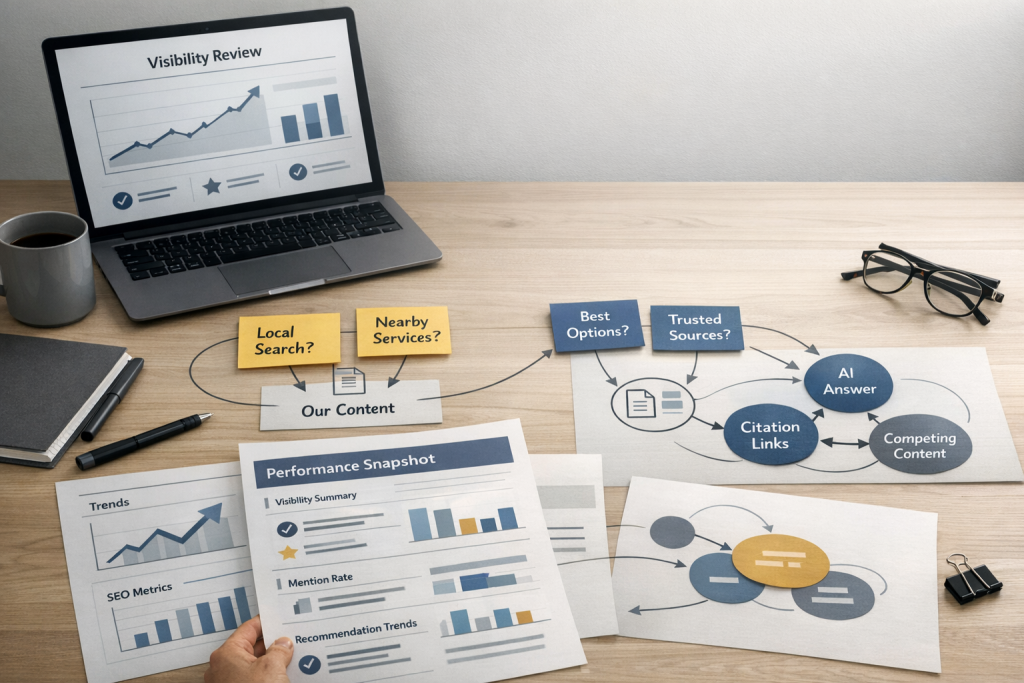
How to Tell Whether Your GEO Campaign Is Actually Improving AI Visibility
Most GEO reports tell you very little about whether your campaign is working. A handful of screenshots showing your brand in a ChatGPT answer, a count of URLs that appeared in AI-generated citations, a month-over-month chart trending upward — none of this, taken alone, is evidence of meaningful progress. It might be noise.
The real question behind every GEO investment is sharper than most reports answer: Is my brand appearing more often, more prominently, and more accurately when buyers ask AI systems the questions that lead to purchase decisions? And if it is, can you distinguish that from random fluctuation?
This guide covers what actual GEO measurement requires, which signals matter, which ones mislead, and how to build a monitoring process that gives your leadership team something worth reviewing each month — without adding another dashboard, another tool, or another internal workflow to manage.
Why GEO Measurement Works Differently Than SEO Measurement
SEO measurement has well-established infrastructure. Google Search Console surfaces impressions, clicks, and average position. Analytics platforms capture organic sessions, landing pages, and conversions. The data is imperfect, but the feedback loop is relatively direct: content gets published, indexed, found, and measured.
GEO measurement does not have that infrastructure. Here is why:
- AI systems do not reliably pass referral data. When someone reads a ChatGPT or Gemini answer that mentions your brand, there is often no click, no referral URL, and no session recorded in your analytics. The discovery happened — your tracking tools just did not see it.
- AI answers are not fixed outputs. The same prompt can produce different answers on different days, across different sessions, and for different users. A single observation is not a measurement — it is a data point of one.
- There is no position number to track. In traditional search, you can monitor whether you rank third or seventh for a given keyword. In AI-generated answers, your brand might be mentioned first, mentioned last, cited without being named, named without being recommended, or absent entirely — and any of those states can shift the next time the same question is asked.
- Each platform operates independently. ChatGPT, Google Gemini, Perplexity, Claude, and Google AI Overviews each use different models, different retrieval logic, and different source selection behavior. Strong visibility on one platform does not carry over to another.
This structural difference is why teams that carry SEO reporting habits into GEO campaigns end up confused. The measurement approach has to change because the system being measured is fundamentally different.
The Ghost Citation Problem: When Your URL Appears but Your Brand Does Not
One of the most common blind spots in GEO reporting is treating every citation as a meaningful win. It is not.
A ghost citation occurs when an AI system references your URL as a source but never mentions your brand anywhere in the answer itself. The reader receives a response that describes a solution, outlines a process, or explains a category — and your page sits in the footnotes. Your company name, your product, your service? Never surfaced. The reader has no reason to click, no reason to remember you, and no connection between the answer they received and your business.
Practitioners who track AI-generated answers at scale consistently find that a meaningful share of citations function as background sourcing only, with the brand never appearing in the answer text. A GEO report that tallies citations without separating brand-visible from brand-invisible appearances overstates actual visibility.
A useful GEO measurement process distinguishes between these outcomes clearly:
- Was your URL referenced as a source?
- Was your brand named in the answer text?
- Was your brand described accurately?
- Was your brand recommended, positioned favorably, or presented as a leading option?
These are not interchangeable outcomes. Treating them as equivalent is one of the fastest ways to misread your actual AI visibility position.
The Four Stages of AI Visibility
Not all AI visibility carries equal weight. Understanding where your content sits in the AI answer pipeline helps you interpret what your measurement data actually means.
Stage 1: Your Content Is Retrieved
The AI system’s retrieval process pulls your page into its working context. This indicates your content was accessible, relevant enough to be selected, and structured clearly enough for the system to process. But retrieval alone does not mean your content shaped the answer. Many retrieved pages are set aside during answer generation.
Stage 2: Your Domain Is Cited
Your URL appears in the source list or footnotes attached to an AI-generated answer. This is a step beyond retrieval — the system found your content useful enough to reference. But as noted above, a citation does not mean your brand was named or that the reader made any connection between the answer and your business.
Stage 3: Your Brand Is Named
The AI answer explicitly mentions your company, product, or service by name. This is where meaningful visibility begins. The reader now associates the answer with your brand. Whether that mention is favorable, neutral, or negative still matters — but being named is the threshold where AI visibility starts functioning like a real discovery channel.
Stage 4: Your Content Shapes the Answer
This is absorption — the AI system does not merely cite your page but draws on your content, framework, data, or explanation as the foundation for the answer it produces. When absorption occurs, your expertise is embedded in the response itself. This is the highest-value form of AI visibility because it positions your brand as the source of the authoritative answer, not just a background reference.
A strong GEO measurement process tracks movement across these stages over time. Advancing from Stage 1 to Stage 3 for a defined set of buyer questions is a meaningful signal. Remaining at Stage 2 for several months suggests the content is being retrieved but is not structured, specific, or authoritative enough to earn brand-level visibility.
Building the Measurement Foundation: The Prompt Library
You cannot measure AI visibility without a structured, repeatable set of prompts. This is the prompt library — the functional equivalent of a keyword tracking list for GEO.
What Kinds of Prompts to Include
A useful prompt library covers the questions your actual buyers ask when they use AI systems to research, compare options, or reach decisions in your category. These typically fall into five types:
- Buyer-intent prompts: Questions a prospective customer would ask before hiring, purchasing, or engaging. Example: “What should I look for when choosing a commercial HVAC maintenance provider in Phoenix?”
- Comparison prompts: Questions that ask for options, alternatives, or ranked lists. Example: “Which B2B content agencies focus on AI search visibility?”
- Problem-and-solution prompts: Questions that describe a specific pain point and ask what to do about it. Example: “My site performs well in Google but doesn’t appear in ChatGPT answers — how do I fix that?”
- Brand-named prompts: Questions that include your brand name directly. Example: “What does CiteHarbor do?” These reveal whether AI systems hold accurate information about your business.
- Brand-absent prompts: The same questions as above, but without your brand name. These test whether AI systems surface your brand organically when a buyer does not already know who you are.
Brand-absent prompts are the most important category. They simulate the actual discovery scenario — a buyer who does not yet know your name, searching for a solution you provide.
How Many Prompts and How Often to Run Them
A prompt library for a typical B2B service business might include 30 to 60 prompts. Larger categories, multi-location operations, or businesses with several distinct service lines may require more. The goal is to cover the buyer questions that matter most — not to track every conceivable query.
Because AI answers shift, a single run produces a data point, not a trend. Repeated runs over time produce interpretable patterns. Monthly monitoring is the minimum cadence needed to identify real trends. Weekly monitoring offers more granular signal but demands more operational capacity.
Which Platforms to Test Across
At minimum, track across ChatGPT, Google Gemini, and Perplexity. Google AI Overviews should be monitored when they surface for your category. Claude is worth including if your buyer audience uses it for research. Each platform retrieves, processes, and generates answers differently, so visibility on one does not reliably predict visibility on another.
What to Record for Each Run
For each prompt, on each platform, in each monitoring cycle, capture:
- Whether your brand was mentioned by name
- Whether your URL was cited as a source
- Whether your brand was recommended, compared, or merely referenced in passing
- The position and prominence of your mention within the answer
- Whether the description of your brand was accurate
- Which competitors appeared in the same answer
- The overall tone toward your brand in the response
This data set, built up over months, is what makes GEO measurement actionable. Without it, you are estimating.
The Core Metrics That Actually Tell You Something
Not every number you can extract from AI monitoring is worth tracking. These are the metrics that give operators real signal.
Mention Rate
Mention rate is the share of prompts in your library where your brand is named in the AI-generated answer. This is the most fundamental GEO metric. A mention rate of 15% means your brand appears by name in roughly 15 out of every 100 monitored prompts. Tracking this figure monthly reveals whether your campaign is building presence or plateauing.
Recommendation Rate
Recommendation rate is the share of prompts where the AI system positions your brand as a suggested, preferred, or noteworthy option — not simply mentioned in passing. This is a higher bar than mention rate and a more meaningful indicator of how AI systems perceive your authority within your category.
Share of Voice
In the AI context, share of voice measures the proportion of AI-generated answers in your category where your brand appears relative to competitors. If you monitor 50 buyer-intent prompts and your brand appears in 10 while a competitor appears in 25, your share of voice is lower. This competitive framing helps leadership understand positioning, not just presence.
Citation Prominence
Not all citations carry equal weight. Citation prominence captures whether your brand is the primary reference in an answer, one of several sources, or a footnote most readers will skip past. Being the first-named brand in a comparative answer is meaningfully different from appearing as the fourth source at the bottom of a list.
Sentiment and Accuracy
How an AI system describes your brand matters as much as whether it mentions you at all. Accurate descriptions of your services, differentiators, and value proposition are a positive signal. Inaccurate descriptions — misattributed services, wrong category placement, outdated positioning — are a content strategy problem that needs to be addressed even when mention rate looks healthy.
Competitive Position
Competitive position tracks which competitors appear alongside your brand in AI-generated answers and how they are framed relative to you. This is not about attacking competitors — it is about understanding how the AI-mediated market looks to a buyer using these systems for research. When a competitor consistently appears in answers where you are absent, that is a visibility gap worth understanding and addressing.
Measuring Improvement Over Time
A single month of data is not enough to evaluate a GEO campaign. AI visibility measurement is an incremental process, not a snapshot exercise.
Establishing a Baseline Before the Campaign
Before any GEO-oriented content is published or optimization work begins, run the full prompt library across all monitored platforms and record every metric listed above. This baseline reading is the reference point that makes all future measurement meaningful. Without it, you cannot separate improvement driven by your campaign from visibility that already existed before you started.
Reading the Trend, Not the Snapshot
The useful question is never “What is our mention rate this month?” in isolation. The useful question is: “How has our mention rate moved since baseline, and is the direction consistent across multiple monitoring cycles?”
Consider this illustrative example: a B2B services firm begins with a baseline mention rate of 8% across 50 buyer-intent prompts on ChatGPT. After three months of targeted content work, that figure moves to 14%. After six months, it reaches 19%. No single month’s reading is conclusive — but the direction across multiple months is a real signal.
Note: These numbers are illustrative, not benchmarks. Actual results vary by industry, category competitiveness, content quality, and platform behavior.
The Holdout Prompt Concept
One way to test whether your campaign is genuinely driving improvement — rather than simply benefiting from platform-wide changes — is to maintain a small group of prompts that you monitor but deliberately do not optimize for. If mention rate improves on prompts you targeted but holds flat on prompts you left alone, that is stronger evidence the campaign is producing results. This approach borrows from experimental design logic and is not yet standard practice in GEO, but it is a sound method for teams that want more rigorous accountability.
Secondary Signals: Traffic, Branded Search, and Referral Patterns
Because AI-generated answers do not always produce direct referral traffic, secondary signals help fill the attribution gap. These signals do not establish causation, but consistent correlation is worth monitoring alongside your core metrics.
AI Referral Segments in Analytics
Some AI platforms do pass identifiable referral traffic. Building filtered segments in your analytics platform to isolate visits from known AI-search referrers helps you understand which pages AI users land on and what they do after arriving. This data is partial — many AI-assisted discoveries never produce a click — but it is still worth collecting as a directional indicator.
Branded Search Volume as a Correlated Indicator
When AI systems name your brand in answers, some share of users will search for your brand directly afterward. An increase in branded search volume that tracks alongside increased AI visibility is a supporting signal — not proof, but worth monitoring in parallel with your core GEO metrics.
Direct Traffic Patterns
Increases in direct traffic — users who navigate to your site by typing your URL or using a bookmark — can also correlate with brand awareness built through AI discovery. This is an indirect signal and should be read cautiously, but unusual spikes in direct traffic that align with periods of increased AI mention rates are worth flagging in your reporting.
Connecting AI Visibility to Business Outcomes
The hardest part of GEO measurement is connecting AI visibility signals to revenue. This is an honest challenge, not a solved problem.
Self-Reported Attribution
The most straightforward approach is also one of the most effective: add a “How did you hear about us?” field to your lead forms and intake processes, with AI-specific options such as “ChatGPT,” “AI search,” or “an AI assistant pointed me to you.” Self-reported attribution is imperfect, but it captures discovery paths that no analytics tool can track on its own.
Funnel Velocity from AI-Sourced Leads
There is a reasonable hypothesis — grounded in how AI answers function — that leads who discover your brand through an AI recommendation arrive with higher purchase intent than leads from a generic search result. An AI system recommending your brand is effectively offering a third-party endorsement. If your team tracks lead source against close rate and sales cycle length, comparing AI-attributed leads to other sources over time can reveal whether this pattern holds for your business.
What AI-Assisted Pipeline Actually Looks Like
AI-assisted discovery rarely follows a clean referral path. A buyer might ask ChatGPT for recommendations, see your brand mentioned, then search your name directly, then visit your site, then complete a form. In your analytics, that sequence shows up as a branded search visit or a direct visit — not an AI referral. This is why self-reported attribution and correlated signal analysis both matter. The attribution trail is messier than traditional channels, and treating it otherwise produces bad reporting.
What a Useful GEO Report Actually Looks Like
A useful monthly GEO report should give a leadership team clarity in under five minutes. It should not require a login, a dashboard walk-through, or a training session to interpret.
What to include:
- Current mention rate, recommendation rate, and share of voice compared to baseline
- Month-over-month trend direction for each core metric
- Platform-level breakdown showing where visibility is strongest and where it is weakest
- Competitive position summary identifying which competitors appear most frequently
- Sentiment and accuracy flags — any instances where AI systems describe the brand incorrectly
- Content actions taken during the period and the visibility targets they were aimed at
- Secondary signal summary: AI referral traffic, branded search trends, self-reported attribution data
What to stop including:
- Raw citation counts presented without context
- Screenshots of individual AI answers offered as proof of success
- Vanity metrics that look impressive but do not connect to visibility trends
- Charts showing movement without any explanation of whether that movement is meaningful or noise
A report built this way gives an executive team what they actually need: a clear answer to “Is this working, and what should we do next?”
The Volatility Problem: Why Consistent Measurement Matters More Than Any Single Reading
AI platforms update their models, revise retrieval logic, and shift source selection behavior — sometimes substantially and without advance notice. A brand that appeared in 30% of monitored prompts one month might appear in 18% the next, not because the GEO campaign underperformed, but because the platform changed how it handles that query category.
This volatility is real, and it is one of the most common reasons teams lose confidence in GEO measurement. The answer is not to stop measuring. The answer is to measure consistently enough that you can distinguish between campaign-driven trends and platform-driven fluctuation.
A single month’s dip is not a failure. A single month’s spike is not a victory. Three to six months of directional data, tracked across multiple platforms against a properly established baseline — that is where reliable insight lives.
This is also why monitoring cadence matters. Teams that check AI visibility once a quarter are working with too little data to draw conclusions. Monthly monitoring is the minimum that produces interpretable trends. More frequent monitoring adds granularity but requires dedicated operational capacity to sustain.
Why the Operational Burden of Measurement Matters
Everything described in this guide — building the prompt library, running it across multiple platforms each month, recording structured data for every prompt, tracking competitive appearances, monitoring sentiment and accuracy, correlating secondary signals, assembling a coherent report — is real work. It is not something a marketing team can handle with a spreadsheet and 30 spare minutes a month.
This is the part most GEO measurement guides skip entirely. They describe what to track without addressing who does the tracking, how much time it actually takes, or what happens when the team responsible is already stretched across SEO, paid media, content production, and reporting for several other channels.
In practice, most teams end up in one of three places:
- They start tracking manually, keep it up for a month or two, then stop when other priorities take over
- They buy a monitoring tool and add another dashboard to the stack that nobody reviews on a consistent basis
- They hand it off to an agency that treats it as a peripheral add-on rather than a core deliverable
None of these approaches produces the kind of sustained, structured measurement that makes GEO data genuinely useful for decision-making.
This is the problem CiteHarbor was built to solve. CiteHarbor manages the core AI visibility workflow — from the initial baseline audit and buyer-question research through content creation, WordPress publishing, social distribution, monthly citation tracking across ChatGPT, Gemini, Perplexity, Claude, and Google AI Overviews, competitor citation monitoring, and branded PDF performance snapshots delivered monthly. Clients do not manage a dashboard, run prompts, or assemble reports. The measurement process runs consistently because it is built into a managed service, not layered onto an already overloaded internal team.
Frequently Asked Questions
How do I check how my brand appears in AI-generated answers?
Start by entering buyer-relevant prompts manually into ChatGPT, Gemini, Perplexity, and other AI platforms your audience uses. Note whether your brand is mentioned, cited, recommended, or absent. For structured, repeatable measurement, you need a prompt library covering your key buyer questions, run consistently across platforms on a defined schedule. Manual spot-checks give you a snapshot; structured monitoring gives you a trend.
Which AI visibility metrics should executives review?
Executives should focus on mention rate, recommendation rate, share of voice relative to competitors, sentiment and accuracy of brand descriptions, and trend direction over time. Raw citation counts and individual screenshots are not useful for executive decision-making. What matters is whether the brand is appearing more often, more accurately, and more favorably than it was at baseline.
How often should AI citations be monitored?
Monthly is the minimum cadence for identifying reliable trends. Because AI answers fluctuate, quarterly monitoring produces too little data to separate real improvement from noise. Weekly monitoring can be valuable in competitive categories but requires dedicated operational capacity to sustain.
What is the difference between a citation and a recommendation in AI search?
A citation means the AI system listed your URL or domain as a source used in generating the answer. A recommendation means the AI system specifically named your brand as a suggested or preferred option for the user. Many citations are ghost citations — your page is sourced, but your brand is never mentioned by name in the answer. Recommendations carry far more visibility value than citations alone.
How long does it typically take to see GEO results?
There is no standard timeline, and any specific promise would be misleading. Some brands see measurable changes in mention rate within two to three months of structured content work. Others take longer, depending on category competitiveness, the quality and depth of existing content, and how AI platforms weight sources in that space. Consistent measurement over a six-month period provides the most reliable picture of whether a campaign is producing results.
Can I measure GEO without specialized tools or services?
You can begin with manual prompt testing and a spreadsheet. This is useful for initial exploration but difficult to sustain at the cadence and consistency that GEO measurement requires. Structured tracking needs a defined prompt library, regular multi-platform monitoring, competitive tracking, and organized reporting — which is where most teams either add a tool to their stack or engage a service partner that handles the process end to end.
What This Means for Your Team
GEO measurement is not impossible, but it is genuinely different from what most marketing teams are accustomed to. The signals are less direct, the data requires more interpretation, the platforms behave inconsistently, and the operational burden of doing it properly is real.
The teams that get this right tend to share a few characteristics: they establish a proper baseline before making any campaign claims, they track the metrics that matter rather than the ones that are easiest to collect, they accept that AI visibility data rewards patience and trend analysis over quick reads, and they build measurement into a sustained process rather than treating it as an occasional check-in.
If your team is evaluating whether its GEO campaign is working — or whether a GEO investment is worth starting — the first step is understanding where you stand right now. A structured baseline audit across the AI platforms your buyers use, with clear metrics, competitive context, and honest analysis, gives you the foundation that every reliable measurement depends on.
CiteHarbor runs that baseline audit as part of a 2-week free trial — no credit card required. You will receive a clear picture of where your brand currently appears, where it is absent, which buyer questions matter most, and how your visibility compares to competitors. No dashboard to manage. No software to learn. Just a clear starting point.