Do You Need a Separate Content Strategy for Perplexity Visibility?
You do not need a separate content strategy for Perplexity, but you do need to adapt how you structure, refresh, and attribute content for AI-search citation. This article explains what transfers from SEO, what needs to change, and how to measure visibility over time.
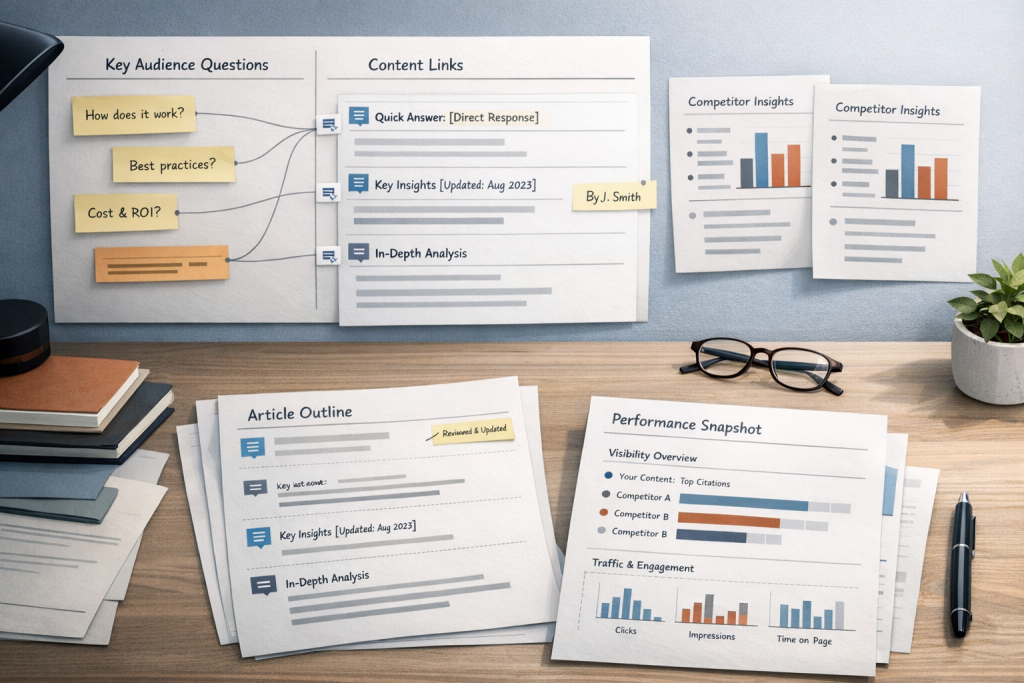
Do You Need a Separate Content Strategy for Perplexity Visibility?
The short answer is no — a full rebuild is not what Perplexity requires. What it does require is a clear understanding of where Perplexity diverges from Google, because those divergences have real consequences for how you structure content, how frequently you refresh it, and how clearly you signal the expertise behind it. The majority of a well-run SEO program transfers without modification. The gap between traditional search content and Perplexity-ready content is genuine but narrower than the industry chatter implies — and that gap is precisely why brands with solid Google rankings sometimes go entirely uncited in Perplexity answers.
This article walks through what carries over from your existing program, what requires deliberate adjustment, and how to measure whether those adjustments are producing results. If you are a CMO, SEO director, content lead, or product marketer with an active search investment, this is the operational breakdown worth reading before committing to a new direction.
How Perplexity Retrieves Content Differently from Google
The question only matters because Perplexity operates on a fundamentally different retrieval model than Google. Getting the mechanics right is the fastest path to understanding what actually needs to change.
Live Retrieval Instead of Pre-Built Rankings
Google’s model is well understood: it crawls the web continuously, builds a persistent index, and scores pages against incoming queries using signals that include link authority, relevance, and hundreds of other factors. A user’s search returns a ranked list drawn from that pre-existing index.
Perplexity works differently at a structural level. Each time a user submits a question, Perplexity queries the live web, pulls content from multiple sources in that moment, synthesizes a response, and surfaces the sources it drew from. There is no pre-ranked list waiting to be served. Your content is being evaluated at query time — not during a crawl that happened last week.
The practical consequence: recency, clarity, and structural accessibility carry more immediate weight than they typically do in traditional search.
How PerplexityBot Processes Your Pages
Perplexity operates its own web crawler, PerplexityBot, to fetch content from across the web. Where Google evaluates a page holistically as a rankable document, PerplexityBot approaches pages differently — it segments content into discrete sections and assesses whether individual segments contain direct, extractable answers to the question at hand.
The implication most content programs overlook: a page can be genuinely well-written and still produce zero Perplexity citations if its sections are not independently coherent enough to be pulled and attributed on their own. Every major section needs to hold up as a standalone answer unit, not merely as a supporting element within a longer argument.
Publication Dates as a Visible Trust Signal
When Perplexity cites a source, it frequently displays that source’s publication or update date alongside the citation — visible to the end user, not buried in metadata. This appears to influence source selection when multiple pages address the same question. A page with a recent, substantive update tends to carry more weight than an older page that has sat untouched, even when the older page has stronger external link authority.
For content teams, this reframes freshness from a ranking hygiene task into a visible credibility signal that users can see and weigh themselves.
What Transfers Directly from Your Existing SEO Program
A functioning SEO or content program already generates significant Perplexity-relevant value. Here is what applies without modification.
Established Authority and Link Signals
Perplexity draws from the open web, and pages with genuine authority — built through external citations, consistent publishing, and recognition from credible sources — tend to surface more reliably than thin or newly minted pages with no external track record. The authority your program has already built is an active asset.
Topical Depth and Content Coverage
If your content program has built out clusters around core subject areas — approaching a topic from multiple angles, with interlinked pieces that reinforce one another — that depth carries over. Perplexity’s retrieval tends to favor sources that demonstrate sustained, substantive engagement with a subject over sites that address it once in a surface-level post.
Technical Accessibility
A site that is technically sound for Google — clean HTML, reasonable load performance, functional internal linking, accurate canonical configuration — is generally accessible to PerplexityBot as well. One area worth verifying: content that relies heavily on client-side JavaScript rendering or lives inside PDFs may not be as reliably accessible to PerplexityBot as it is to Googlebot. Core content should be available in standard, crawlable HTML.
It is also worth confirming that your robots.txt file does not restrict PerplexityBot. A blocked crawler means no citations, regardless of content quality.
Formatting Already Optimized for Direct Answers
Content structured for Google’s featured snippets — with clear heading hierarchies, concise paragraphs, bulleted lists, and answers placed near the top of sections — translates directly to Perplexity’s extraction model. If your team has already invested in that kind of formatting discipline, you are not starting from scratch.
What Specifically Needs to Change
This is where the substantive work lives. These are not cosmetic adjustments — but they are also not a wholesale strategy replacement. Skipping them is the most common explanation for why brands with strong SEO programs still fail to appear in Perplexity answers.
Leading with the Answer: Structure for Extraction, Not Narrative Build
Traditional long-form SEO content often constructs toward a conclusion — context first, answer later. Perplexity’s chunking model inverts that priority. The opening sentences of each section carry outsized weight because that is what PerplexityBot is most likely to extract as a discrete answer block. An answer buried in the fourth paragraph of a seven-paragraph section may not be retrieved at all.
The required adjustment: open every major section with the direct answer or central claim, then develop the supporting context beneath it. This is not about simplifying your content — it is about placing the substance where the retrieval system can find it.
Treating Freshness as an Ongoing Editorial Commitment
Most SEO programs approach content updates reactively — revisiting pages when rankings slip or traffic declines. For Perplexity visibility, freshness needs to be a proactive, scheduled discipline rather than a maintenance response.
This does not mean touching publish dates without changing the underlying content. It means building regular review cycles into your editorial calendar — checking that information is current, examples are still relevant, and the visible update date reflects genuine editorial work. Because Perplexity surfaces those dates to users, a stale timestamp next to a competitor’s recently revised page creates an immediate credibility disadvantage.
Entity Clarity: Establishing Who Is Speaking and Why It Matters
Google’s E-E-A-T framework — experience, expertise, authoritativeness, trustworthiness — has long shaped how quality is evaluated in search. Perplexity appears to weight analogous signals, with particular attention to entity clarity: whether the system can identify who produced a piece of content and why that source carries relevant authority on the topic.
In practice, this means:
- Named author attribution on articles, linked to author pages that establish relevant credentials
- Organization schema that clearly identifies your business in structured data
- Person schema for individual contributors where appropriate
- Consistent use of your organization name and named experts throughout your content
Content that could plausibly have been published by any anonymous source gives Perplexity less reason to select it over a competitor with clearer attribution.
Targeting the Questions Buyers Actually Ask
Conventional keyword research is built around search phrases and volume data. Perplexity users tend to submit questions in full, conversational, often multi-part form — the kind of specific, decision-stage queries that keyword tools underweight or miss entirely.
Effective content planning for Perplexity requires identifying the actual questions your buyers are asking at different stages of evaluation — including comparison questions, follow-up questions, and questions that surface right before a purchase decision. This buyer-question research differs from keyword research in both method and scope, and it produces a meaningfully different content roadmap.
Creating Content That Is Worth Citing
Because Perplexity cites its sources, it is actively choosing which source to attribute each claim to. Pages that offer specific, verifiable, clearly attributed information are more likely to be selected than pages that restate common knowledge without contributing anything distinct.
A useful test: for any claim your content makes, ask whether it is concrete and specific enough to be quoted directly. Vague assertions about industry trends are not citable. Precise descriptions of how a system works, what a process requires, or what a decision involves are. Specificity and clear attribution are what separate a citable source from filler content that gets synthesized away.
The Underlying Shift in How You Think About Visibility
The tactical adjustments above are consequential, but they follow from a more fundamental change in orientation.
Traditional SEO asks: How do I get this page to rank for this keyword?
Perplexity-style visibility asks: Is my brand the kind of source this system will discover, trust, and cite when a relevant question comes in?
That is not a semantic difference. It changes what you build and what you measure. The ranking model optimizes individual pages for individual queries. The citation model builds a body of content that establishes your organization as a credible, quotable authority across the range of questions your buyers ask.
This reorientation does not replace SEO. It operates alongside it. But it does shift content planning priorities — which topics you cover, how you structure what you publish, and what counts as a meaningful outcome.
How to Know If It Is Working: Measuring Perplexity Visibility
Most guidance on Perplexity optimization stops before addressing measurement. Adjusting your content is only useful if you can determine whether those adjustments are producing results.
What to Track
- Brand citation frequency in AI-generated answers: How often does your organization appear when Perplexity responds to questions in your category? This is your core visibility baseline.
- Competitor citation patterns: Which competitors are being cited for the same buyer questions where your brand is absent? Where specifically are they appearing and you are not?
- Referral traffic from AI platforms: When Perplexity links to your content as a cited source, that traffic is measurable in your analytics. Track it as a distinct channel.
- Buyer-question coverage: Of the questions most relevant to your buyers’ decisions, how many does your content answer with enough directness and clarity to be extractable?
Auditing Your Existing Content for Perplexity-Readiness
A practical starting audit evaluates your highest-value pages against the following criteria:
- Does each major section open with a direct answer rather than building toward one?
- Are individual sections coherent enough to be extracted and cited without surrounding context?
- Is a publication or substantive update date visible on the page and reasonably recent?
- Is there clear author or organizational attribution?
- Does the page use accurate structured data — Article, Organization, or Person schema as appropriate?
- Is the primary content rendered in crawlable HTML rather than JavaScript or embedded PDFs?
- Does robots.txt permit PerplexityBot access?
A page that fails more than two of these checks is unlikely to earn Perplexity citations, regardless of where it ranks in Google.
Establishing a Monitoring Cadence
Perplexity’s citation behavior is not fixed. As new content enters the web and the system continues to evolve, which sources get cited — and for which questions — shifts over time. Monthly monitoring is a practical minimum: tracking your brand’s citation presence against a consistent set of buyer questions, comparing against competitors, and identifying emerging gaps before they compound.
This is not a one-time audit. It is a recurring feedback loop that informs both content production and update priorities.
Why the Operational Reality Is Harder Than the Concept
The adjustments described above are not conceptually complicated. The challenge is execution at scale, sustained over time.
Buyer-question research is not a one-time deliverable — it requires continuous updating as your market’s questions evolve across multiple AI platforms. Content restructuring means revisiting existing pages, not just producing new ones. Freshness management requires editorial calendar discipline layered on top of existing production commitments. Entity signal work involves structured data and author pages that most content teams do not actively maintain. Citation tracking requires monitoring AI platforms monthly with enough consistency to surface meaningful trends.
For teams already managing SEO, paid media, social, and content production, absorbing this as another internal workstream typically means it gets deprioritized or executed inconsistently.
This is the operational problem CiteHarbor was built to address. CiteHarbor manages the full workflow — from AI visibility auditing and buyer-question research through article creation, WordPress publishing, social distribution, competitor citation monitoring, and branded monthly performance reporting — so your team does not need to manage another dashboard, another content calendar, or another roster of freelancers. The output is a clear monthly snapshot of where your brand stands, delivered as a branded PDF rather than a login to another platform.
A Practical Starting Sequence
If you are evaluating how to adjust your content approach for Perplexity, here is a realistic order of operations:
- Establish your current visibility baseline. Submit the questions your buyers ask directly to Perplexity. Document where your brand appears, where competitors appear, and where no one in your category appears at all.
- Identify your highest-value buyer questions. Prioritize questions connected to active purchase decisions over informational queries with high search volume but low commercial intent.
- Evaluate existing content against Perplexity-readiness criteria. Use the audit checklist above to identify which pages need structural revision and which need substantive content updates.
- Restructure high-priority pages. Open sections with direct answers. Add entity signals. Verify structured data accuracy. Confirm PerplexityBot can access the page.
- Build a freshness cadence into your editorial calendar. Determine which pages require regular review and schedule that work explicitly rather than leaving it to reactive maintenance.
- Begin monthly tracking. Monitor brand citations, competitor visibility, and referral traffic from AI platforms. Measure against your baseline and adjust based on what you find.
This is a sustained operational discipline, not a one-time project. Organizations that build this capability — whether in-house or through a dedicated partner — accumulate a compounding advantage as AI-search adoption continues to grow.
Frequently Asked Questions
Is Perplexity optimization different from Google SEO?
Partially. The foundational principles — content depth, clarity, authority, and technical accessibility — apply to both. The meaningful differences lie in how content must be structured for extraction, how frequently it needs to be refreshed, and how entity and attribution signals are weighted. The most accurate framing is that Perplexity optimization is a strategic layer on top of SEO, not a replacement for it.
Does my existing SEO content work for Perplexity?
Some of it likely does — particularly content that is well-structured, recently updated, clearly attributed, and technically accessible to crawlers. Content that ranks well in Google can still be invisible to Perplexity if answers are buried deep within long sections, publication dates are absent or stale, or PerplexityBot cannot access the page.
What is PerplexityBot?
PerplexityBot is the web crawler Perplexity uses to retrieve content from websites. It functions similarly to Googlebot in that it fetches pages from the open web, but it evaluates content differently — prioritizing discrete, extractable sections over holistic page-level ranking. If your robots.txt file blocks PerplexityBot, your content will not appear in Perplexity answers regardless of its quality or authority.
How do I know if Perplexity is citing my content?
You can check manually by submitting the buyer questions most relevant to your business and reviewing which sources Perplexity cites in its responses. Systematic monitoring requires a repeatable process — tracking your brand’s citation presence across a consistent query set over time and comparing against competitors. Citation monitoring is one of the core components of CiteHarbor’s monthly visibility tracking service.
Do I need different content for Perplexity versus ChatGPT?
Not entirely different content, but the emphasis varies by platform. Perplexity queries the live web in real time for every response. ChatGPT’s base model draws from training data, though ChatGPT Search also performs live retrieval. Both reward well-structured, authoritative, clearly attributed content — but Perplexity places more visible weight on recency and source attribution. A well-designed AI visibility program addresses both without requiring separate content inventories for each platform.
How often should I update content for Perplexity visibility?
There is no universal rule, but a reasonable working standard is: as often as the underlying information meaningfully changes, and at minimum quarterly for your highest-priority pages. Updates should reflect genuine editorial work — revised information, current examples, updated data — rather than cosmetic date adjustments. Because Perplexity surfaces update dates to users, a recent timestamp paired with substantively current content creates a visible credibility advantage over competitors with stale pages.
What is GEO and is it the same as Perplexity optimization?
GEO — Generative Engine Optimization — refers to the broader practice of structuring content to improve visibility across AI-powered search and answer systems. Perplexity optimization falls within the GEO category, alongside optimization for ChatGPT, Google Gemini, Claude, and Google AI Overviews. The underlying principles overlap substantially across these platforms, though each has behavioral characteristics that are worth understanding individually.
The Short Version
You do not need a separate content strategy for Perplexity. You need a more precise version of the strategy you already have — one that accounts for how AI answer engines retrieve, evaluate, and attribute content differently from traditional search. The required adjustments are specific: answer placement, freshness discipline, entity signals, buyer-question targeting, and citable specificity. The results are measurable: brand citation frequency, competitor visibility gaps, and referral traffic from AI platforms. The operational challenge is real: this work requires consistent execution across research, content, publishing, tracking, and reporting.
If your team is already stretched across SEO, paid media, and content production, absorbing AI visibility as another internal workstream is often not realistic. CiteHarbor was built specifically for this situation — managing the full execution so you receive a branded monthly performance snapshot rather than another platform to log into.