Does Allowing OAI-SearchBot to Crawl Your Website Help You Appear in ChatGPT Search?
Allowing OAI-SearchBot is necessary if you want your pages to be eligible for ChatGPT search citations, but access alone does not guarantee visibility. This article explains how to configure robots.txt correctly, avoid CDN and WAF blocks, and understand what actually influences citation eligibility.
Does Allowing OAI-SearchBot to Crawl Your Website Help You Appear in ChatGPT Search?
Yes. Allowing OAI-SearchBot to crawl your website is a necessary step for your pages to become eligible to appear in ChatGPT search results. OpenAI states this directly in its own documentation: sites that block OAI-SearchBot will not be shown as sources in ChatGPT search answers.
But crawl access alone does not guarantee your pages will be cited, recommended, or surfaced for any specific query. Allowing the bot is the entry ticket. What happens after that depends on content relevance, page structure, topical authority, and several technical factors that most coverage of this topic skips entirely.
This article explains what OAI-SearchBot actually does, how it differs from OpenAI’s other crawlers, how to configure access correctly, why your robots.txt file may not be the only barrier, and what else influences whether an eligible page actually gets cited in a ChatGPT response.
What OAI-SearchBot Is and Why It Matters
OAI-SearchBot Is OpenAI’s Search Indexing Crawler
OAI-SearchBot is the specific web crawler OpenAI uses to index pages for its ChatGPT search feature. When a ChatGPT user asks a question that triggers a web search, ChatGPT retrieves real-time information from across the web. OAI-SearchBot is the agent that makes this retrieval possible by crawling and indexing pages in advance.
This crawler is distinct from OpenAI’s model-training crawler. OAI-SearchBot exists specifically to support the search function inside ChatGPT, not to collect data for training large language models.
How ChatGPT Search Uses Crawled Content
ChatGPT search operates as a real-time web retrieval system. When a user’s query requires current information, product comparisons, service recommendations, or factual verification, ChatGPT searches the web, retrieves relevant pages, and synthesizes an answer that includes source citations and links.
If OAI-SearchBot has not been allowed to crawl your site, your pages are not in the pool of sources ChatGPT can draw from during this process. Your content effectively does not exist in ChatGPT’s search layer, regardless of how relevant, authoritative, or well-written it may be.
The Three OpenAI Crawlers You Need to Understand
OpenAI operates three distinct web crawlers. Each has a different purpose, and each can be controlled independently in your robots.txt file. Conflating them is one of the most common mistakes businesses make when configuring AI crawler access.
| Crawler | User Agent | Purpose | What Blocking It Means |
|---|---|---|---|
| OAI-SearchBot | OAI-SearchBot | Indexes pages for ChatGPT search results | Your pages will not appear as sources in ChatGPT search answers |
| GPTBot | GPTBot | Collects data for AI model training | Your content will not be used for training future OpenAI models |
| ChatGPT-User | ChatGPT-User | Fetches pages in real time during a live chat session when a user browses or clicks a link | ChatGPT cannot retrieve your page live during a conversation |
The critical point: you can allow OAI-SearchBot while blocking GPTBot. These are independent decisions. If you want your pages eligible for ChatGPT search visibility but do not want your content used for model training, you can configure your robots.txt to permit one and deny the other.
How to Allow OAI-SearchBot in Your robots.txt
The Basic Allow Directive
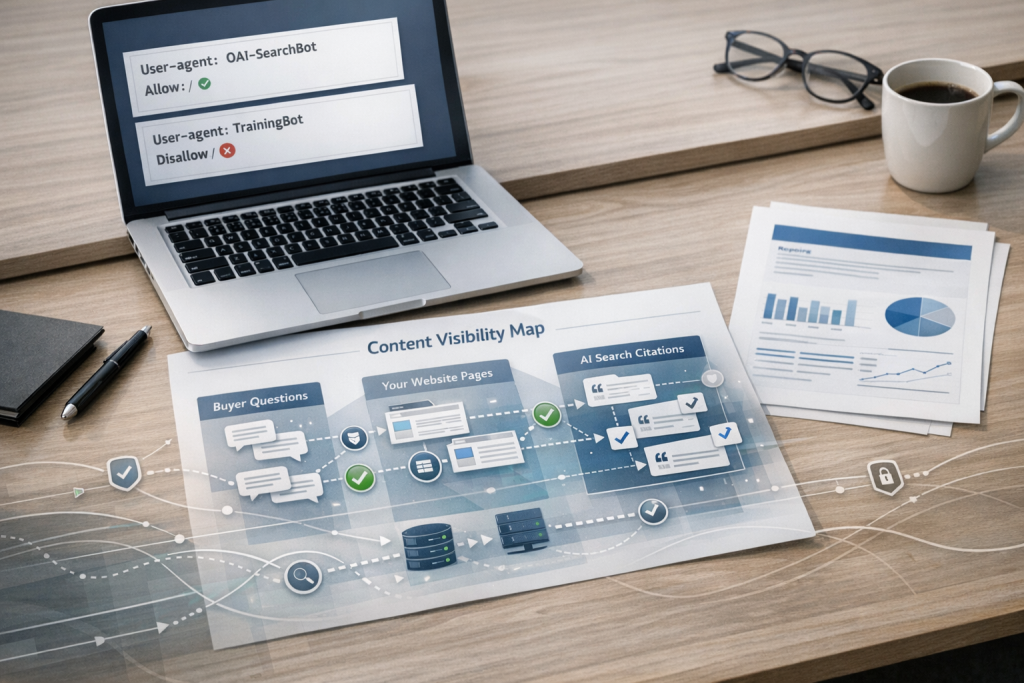
To allow OAI-SearchBot to crawl your entire site, add the following to your robots.txt file:
User-agent: OAI-SearchBot
Allow: /
If your robots.txt does not mention OAI-SearchBot at all, and you do not have a blanket disallow rule for all bots, the crawler is permitted by default. However, explicitly allowing it removes ambiguity and ensures your configuration is clear.
Allowing OAI-SearchBot While Blocking GPTBot
Many businesses want search visibility in ChatGPT without contributing content to model training. This configuration handles that:
User-agent: OAI-SearchBot
Allow: /User-agent: GPTBot
Disallow: /
This tells OpenAI’s systems that your pages are available for ChatGPT search indexing but should not be used for training data collection. OpenAI’s documentation confirms that these directives are respected independently.
What Happens If You Block OAI-SearchBot
If your robots.txt blocks OAI-SearchBot, either explicitly or through a blanket disallow rule, your pages become ineligible for ChatGPT search results. They will not be cited as sources. They will not appear as links in ChatGPT’s answers. OpenAI states that blocked pages may still appear as navigational links in some cases, but they will not be shown as source citations in search-generated responses.
This is not a subtle distinction. For businesses that rely on being found when prospects ask AI systems for recommendations, blocking OAI-SearchBot removes you from the conversation entirely.
robots.txt Is Not the Only Access Layer
This is where most coverage of the topic stops, and where the most important practical gaps begin. Configuring your robots.txt correctly is necessary, but it may not be sufficient. Two additional layers can block OAI-SearchBot even when your robots.txt explicitly allows it.
CDN and WAF Bot Protection Can Block OAI-SearchBot Silently
If your website uses Cloudflare, Sucuri, or another content delivery network or web application firewall with bot-management features, those systems may block OAI-SearchBot at the network level before the crawler ever reaches your server or reads your robots.txt file.
This happens because many CDN and WAF configurations include aggressive bot-filtering rules that challenge or block automated requests. OAI-SearchBot is an automated crawler. If your security layer treats it the same way it treats scraper bots or spam crawlers, it gets blocked silently.
The result: your robots.txt says “allowed,” but OAI-SearchBot never actually reaches your pages. You have no ChatGPT search eligibility and no obvious error message telling you why.
OpenAI’s Published IP Ranges and Why Allowlisting Matters
OpenAI publishes the IP ranges used by its crawlers. If your CDN or hosting provider supports IP-based allowlisting, adding OpenAI’s published ranges ensures that OAI-SearchBot can pass through your security layer and reach your site.
This is a step that most articles on this topic do not mention, but it is a real-world blocker for many sites. If you have configured robots.txt correctly and are still not seeing evidence of OAI-SearchBot crawls, a CDN or WAF block is the most likely cause.
How to Verify Whether OAI-SearchBot Is Actually Reaching Your Site
Configuration is only useful if it is working. Here is a practical checklist for confirming that OAI-SearchBot can access your pages:
- Check your robots.txt file directly. Visit yourdomain.com/robots.txt in a browser. Confirm that OAI-SearchBot is either explicitly allowed or not blocked by a blanket disallow rule.
- Review your server access logs. Search for the user agent string “OAI-SearchBot” in your server logs. If the bot is reaching your site, you will see entries with that agent string. If there are no entries, the bot is being blocked before it arrives.
- Check your CDN or WAF dashboard. If you use Cloudflare or a similar service, look at the bot traffic or firewall events section. Check whether requests from OpenAI’s IP ranges are being challenged, rate-limited, or blocked.
- Review OpenAI’s published IP ranges. Compare the IPs in your server logs against OpenAI’s published crawler IP list to confirm that the traffic you see is genuinely from OAI-SearchBot and not a spoofed user agent.
- Test with a new or updated page. Publish a new page, ensure it is linked internally, and monitor whether OAI-SearchBot crawls it within a reasonable timeframe. This is not instant. Crawl frequency varies and is not publicly documented in detail.
If you complete these steps and find that OAI-SearchBot is not reaching your site despite correct robots.txt settings, your security layer is almost certainly the issue.
Crawl Access Makes You Eligible — It Does Not Guarantee Appearance
This is the most important nuance in the entire topic, and the one that most articles either skip or bury in a footnote.
Allowing OAI-SearchBot to crawl your site makes your pages eligible to be cited in ChatGPT search results. It does not mean your pages will appear for any particular query, or that they will be cited at all.
What Factors Influence Whether an Eligible Page Gets Cited
ChatGPT search uses multiple factors when selecting which pages to surface as sources in a response. While OpenAI has not published a detailed ranking algorithm, observable patterns and OpenAI’s own documentation suggest that the following matter:
- Relevance to the query. The page must actually address what the user asked. Pages that are topically adjacent but do not answer the specific question are less likely to be cited.
- Content clarity and structure. Pages with clear headings, direct answers, and well-organized sections are easier for retrieval systems to parse. A page that buries its answer in the sixth paragraph is less useful to a system that needs to extract a concise response.
- Topical authority. Sites that demonstrate depth on a subject across multiple related pages are more likely to be treated as credible sources on that topic.
- Freshness. For queries where recency matters, recently updated or published pages may be preferred over stale content.
- Page accessibility. Beyond crawl access, the page must load properly, render its main content in accessible HTML, and not rely on JavaScript that prevents content extraction.
None of these factors can be precisely quantified from outside OpenAI’s systems. But the practical implication is clear: allowing OAI-SearchBot is step one, not the entire strategy.
What Appearing in ChatGPT Search Actually Looks Like
When ChatGPT search cites your page, it typically shows up in one of these ways:
- As a source citation link. Your page URL appears as a clickable source alongside ChatGPT’s synthesized answer.
- As a quoted or referenced source. ChatGPT may directly reference your content, brand, or data point within its answer text.
- As a navigational link. In some cases, your site may appear as a link that helps the user navigate to a relevant destination, even if the page was not the primary source for the answer.
For most businesses, the first two categories are what matter. Being cited as a source when a prospect asks ChatGPT for recommendations, comparisons, or solutions in your category is the high-value outcome. But that outcome depends on content quality and relevance, not just crawl access.
What This Means for Your AI Visibility Strategy
Configuring OAI-SearchBot access correctly is a necessary technical foundation. But it is only the technical foundation. What separates businesses that get cited in AI-generated answers from those that do not is the work that happens on top of that foundation:
- Understanding which buyer questions matter. AI search systems respond to real questions from real users. If your content does not address the questions your buyers are actually asking AI engines, crawl access alone will not help.
- Creating content designed for buyer-question coverage. This is not traditional blog production or keyword-targeted SEO content. It is content specifically researched and structured to answer the questions that surface in AI-generated results for your category.
- Tracking whether your brand is actually being cited. Crawl access creates eligibility. But without ongoing monitoring, you have no way to know whether that eligibility is translating into actual visibility. You need a baseline, and you need regular tracking against it.
- Monitoring competitor visibility. Knowing where your competitors appear in AI answers, and where you do not, is essential for prioritizing your content strategy.
This is the work CiteHarbor handles for clients. Not just the robots.txt configuration, but the full AI visibility workflow: auditing where your brand currently appears and where it is missing across ChatGPT, Perplexity, Google Gemini, Claude, and Google AI Overview. Researching the buyer questions that drive AI-generated recommendations in your category. Creating targeted articles designed to improve your brand’s chance of being cited. Publishing to your WordPress site and distributing across your social channels. Tracking citation patterns and competitor visibility monthly. Delivering a branded PDF performance snapshot so you know where you stand without logging into another dashboard.
The differentiator is that CiteHarbor is not a software platform you need to manage. It is a full-service partner that handles the research, content creation, publishing, distribution, tracking, and reporting. You get the visibility strategy without adding another tool, another freelancer, or another internal workflow to manage.
Frequently Asked Questions
Can I allow OAI-SearchBot but block GPTBot?
Yes. OAI-SearchBot and GPTBot are controlled independently in your robots.txt file. Granting access to OAI-SearchBot for ChatGPT search indexing does not require you to also permit GPTBot. If keeping your content out of model training is a priority, you can disallow GPTBot in the same file while leaving OAI-SearchBot fully open. OpenAI’s documentation confirms these are treated as separate directives.
How do I know if OAI-SearchBot is crawling my site?
Check your server access logs for the user agent string “OAI-SearchBot.” If you do not see any entries, the bot is either blocked by your robots.txt, blocked by your CDN or WAF, or has not yet crawled your site. Also check your CDN dashboard for blocked or challenged requests from OpenAI’s published IP ranges.
Does blocking OAI-SearchBot affect my Google rankings?
No. OAI-SearchBot is operated by OpenAI, not Google. Blocking or allowing it has no direct effect on your Google Search rankings. Google uses its own crawlers, including Googlebot, independently. However, blocking OAI-SearchBot does remove your pages from eligibility for ChatGPT search citations.
Does allowing OAI-SearchBot guarantee that ChatGPT will recommend my business?
No. Allowing OAI-SearchBot makes your pages eligible to be cited in ChatGPT search results. Whether they are actually cited for any specific query depends on content relevance, page structure, topical authority, and other factors that OpenAI has not fully disclosed. Crawl access is a prerequisite, not a guarantee.
What is ChatGPT-User and is it different from OAI-SearchBot?
Yes, they are different. ChatGPT-User is the agent OpenAI deploys when ChatGPT needs to retrieve a specific page on demand during an active conversation — for instance, when a user pastes in a URL and asks ChatGPT to read it. OAI-SearchBot, by contrast, crawls pages proactively to build the search index that ChatGPT draws from when answering queries. Both agents can be controlled independently in robots.txt.
Can any agency guarantee a ChatGPT recommendation?
No. No agency, tool, or platform can guarantee that ChatGPT or any other AI system will cite, recommend, or feature your business. AI citation patterns are influenced by many factors, and the internal processes of these systems are not publicly controllable. Any provider claiming guaranteed AI citations should be evaluated with caution. What a responsible partner can do is audit your current visibility, track your baseline, research the buyer questions that matter, create content designed to improve your eligibility, and monitor changes over time.
How should ChatGPT visibility be monitored over time?
ChatGPT visibility monitoring requires regular testing of relevant buyer questions across AI-search environments, tracking which brands are cited in responses, comparing your citation patterns against competitors, and measuring changes against a documented baseline. This is different from tracking Google rankings. It requires a separate monitoring process focused on AI-generated answer patterns rather than traditional SERP positions.
Conclusion
Allowing OAI-SearchBot to crawl your website is a necessary first step for ChatGPT search eligibility. The configuration itself is straightforward. But the full picture includes verifying that your CDN and WAF are not blocking the crawler silently, understanding that crawl access creates eligibility without guaranteeing citations, and recognizing that the real competitive advantage comes from the content, research, and monitoring strategy built on top of that technical foundation.
If you want to know where your brand currently stands in AI-generated answers, where your competitors are appearing, and which buyer questions represent the biggest visibility gaps, CiteHarbor can help. We handle the full workflow: auditing, buyer-question research, content creation, WordPress publishing, social distribution, competitor monitoring, and monthly performance snapshots.